Replay lab
See what a policy change actually changes. Explore 50 recorded public-fixture command cases through two versions of a toy guard. Follow a case, filter the differences, then adjust a sample regression gate.
The corpus has 40 synthetic cases and 10 fully re-authored historical/opaque shapes. This is a teaching example, separate from the current deny floor. It displays checked-in decisions; it does not run commands, contact a model, or measure a live deployment.
RECORDED EVIDENCE / PUBLIC FIXTURE
The interactive report is loading. The recorded summary and reproduction commands below work without JavaScript.
1. Follow a case
Guard v2 exempts help and dry runs, but accidentally drops its git clean rule. Start with the regression, then compare a benign improvement.
2. Try a regression gate
Choose which transitions fail this sample gate. It always checks all 50 cases. These controls change only this browser demonstration.
A transition is not a verdict about safety. Newly allowed help can be an improvement; newly allowed destructive cleanup can be a regression. The case rationale supplies that context.
3. Inspect the evidence
| Command | Label | v1 → v2 | Change |
|---|
No matching cases. Clear the filters or reset the example.
What the recorded run shows
| Transition | Cases | How to read it |
|---|---|---|
| Newly allowed | 4 | Three benign cases improve; one dangerous cleanup case regresses. |
| Newly denied | 1 | The candidate catches the corpus’s force-with-lease case. |
| Unchanged | 45 | An unchanged decision can still be wrong. Inspect the corpus label. |
| Newly indeterminate | 0 | Neither toy hook fails to produce a determinate decision here. |
The default gate fails because it rejects any newly allowed case. These are the toy guards’ recorded decisions on charter-v0.1, not measurements of the current floor. The labels describe this teaching corpus; they are not universal shell-command classifications.
Sources: recorded report, toy guard walkthrough, baseline source, candidate source.
Reproduce it locally
From the repository root, Python 3.11 or newer can reproduce the comparison from recorded decisions:
python -m replay_v0.app replay \
  --baseline recorded:examples/toy-guard/report/baseline/decisions.jsonl \
  --candidate recorded:examples/toy-guard/report/candidate/decisions.jsonl \
  --corpus replay_v0/corpora/charter \
  --output reports/toy-guard-recorded
Expect exit 1 with newly-allowed: 4 in summary.json: the comparison ran and its regression gate failed. The toy guard walkthrough also shows how to invoke the two hooks afresh. Replay sends command text to the policies; it does not execute the recorded commands.
Put the tools together
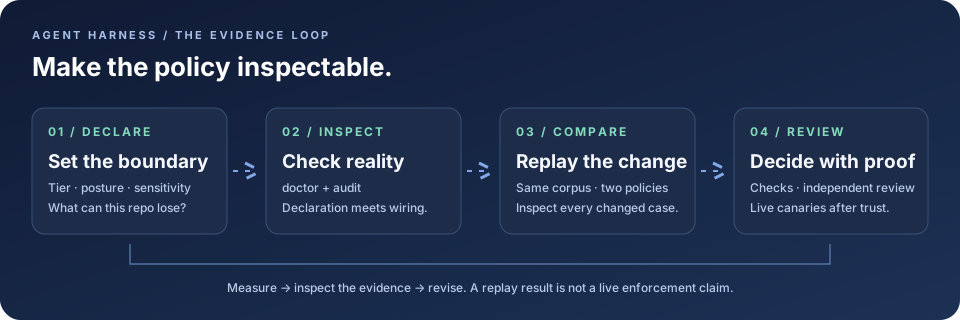
Use doctor and audit to inspect the declaration and wiring. Use replay to measure a proposed policy change on a pinned corpus. Review the changed cases before shipping. Runtime trust and live canaries remain separate evidence; see the floor limits and capability ledger.